Website Spoofing / Clone Site
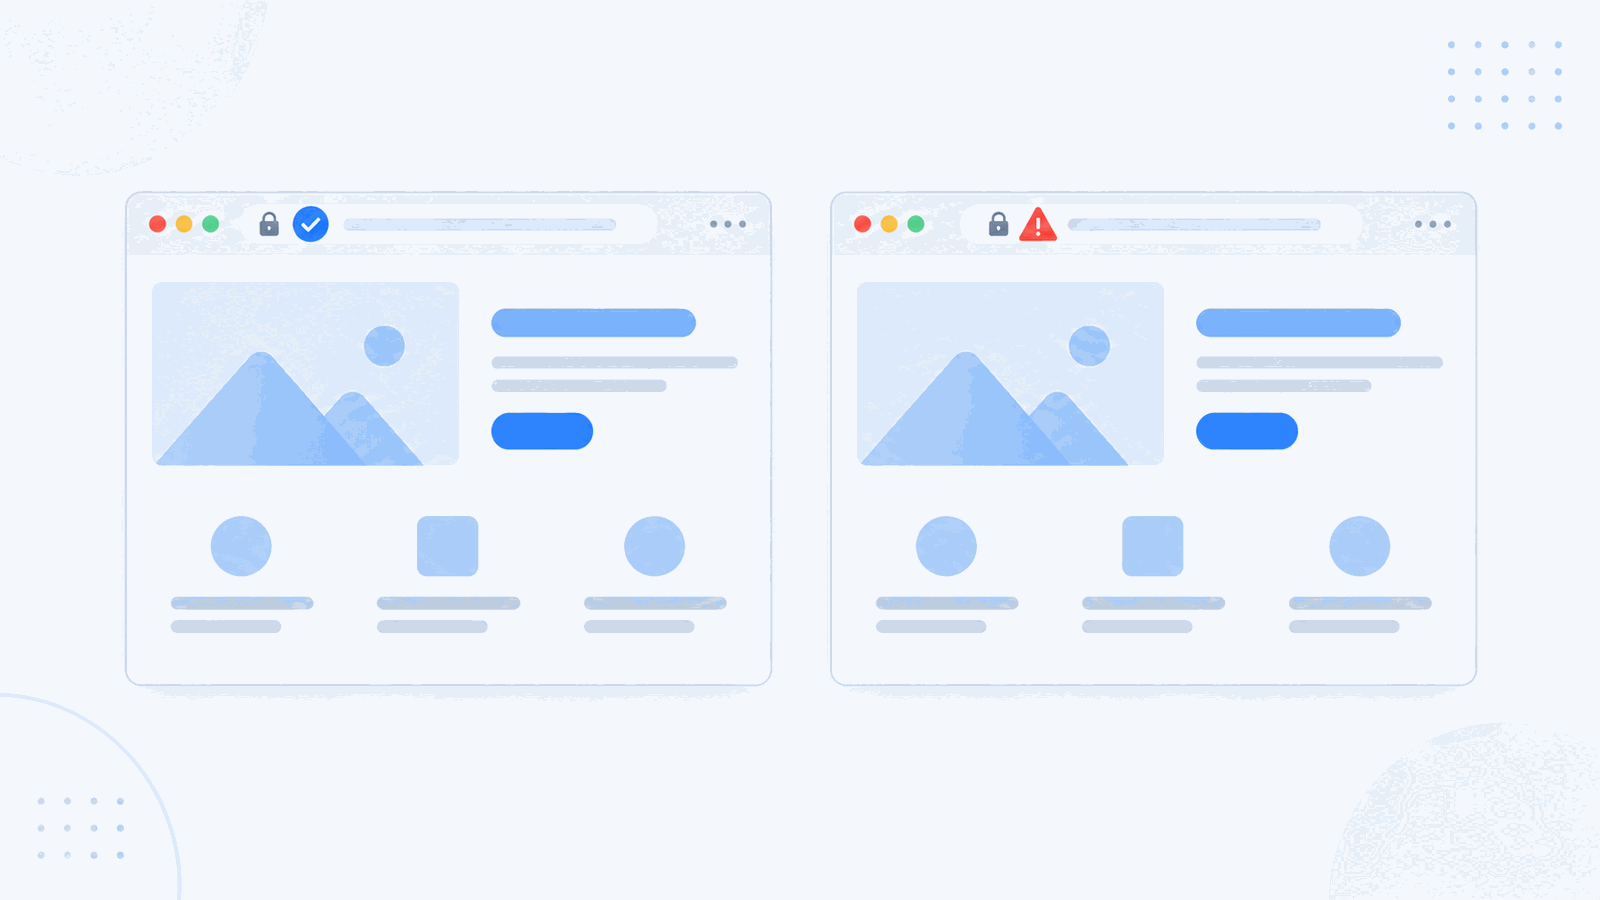
Website spoofing, or site cloning, is the practice of copying a legitimate brand’s website in full, including layout, logos, product pages and checkout flow, then hosting it on a different domain to deceive visitors into believing it is genuine. Unlike typosquatting, which relies on a misspelled or lookalike domain name to catch mistyped traffic, a cloned site copies the actual content and design, so a visitor who lands on it via a phishing link, fake ad or social post sees what looks like the real brand.
What it is
A cloned website is a near-pixel-perfect replica of a brand’s real site. Attackers scrape the HTML, CSS, images and product catalogue from the genuine site, then rehost that copy on infrastructure they control. The visible experience, from the homepage to product listings to the checkout page, can look identical to the original. What differs, invisibly to the visitor, is where the “Buy” button or login form actually submits data: to the attacker’s own payment processor or database, not the brand’s.
This makes clone sites more convincing than a typical phishing page, which often has crude formatting or an obviously fake domain. A well-built clone can pass a casual glance entirely, which is why they’re commonly used both for fraud (fake checkout pages that take payment and never ship) and credential theft (fake login pages for a brand’s customer portal).
How it works
- Scrape and copy: automated tools pull the full front-end of the target site, including HTML, CSS, JS, images and product data, often within minutes.
- Stand up the clone: the copy is hosted on a new domain, a compromised subdomain, or sometimes an app-store-style listing, frequently registered close to a promotional event or a season when the brand runs offers.
- Swap the backend: forms and checkout flows are rewired to route to infrastructure the attacker controls, whether a different payment gateway, a credential-harvesting database, or both.
- Drive traffic: the clone is pushed through phishing emails, fraudulent social/search ads, or messaging-app links, often timed to a sale or product launch when visitors are primed to click quickly.
In practice
Clone sites are a recurring problem around high-demand product drops and festive sales, where attackers stand up a full replica of a retailer’s storefront, matching the branding, product photography and pricing exactly, to intercept shoppers searching for a deal, take payment, and disappear before the brand or customers notice. Because the clone often only needs to survive for the duration of a single sale window, brands frequently discover it only after customer complaints about undelivered orders start arriving.
How Truviss helps
Truviss’s Domain Scanner continuously monitors for newly registered domains and hosted pages that copy a brand’s site structure, branding assets and product catalogue, flagging matches for takedown before a clone can run through a full sale cycle undetected. The same detection layer that catches typosquatted domains also surfaces full-site clones, since content similarity, not just domain spelling, is part of the match.
Related terms
Typosquatting relies on a misspelled or lookalike domain name to catch visitors who mistype a URL. Site cloning copies the actual content, design and checkout flow of the real site, so it can deceive even a visitor who reaches it deliberately through a phishing link or fake ad, regardless of the domain name used.
Yes. Because the clone reuses the brand’s actual images, layout and product copy, visual inspection alone often isn’t enough to spot it. The giveaway is usually in the domain, the payment processor, or small inconsistencies in the checkout flow, not the page design itself.
Clone sites are often built and hosted within hours using automated scraping tools, and many are taken down by the attacker once a sale window ends, before a brand’s manual monitoring catches them. This is why continuous, automated scanning matters more than periodic manual checks.